Codetown
Codetown ::: a software developer's community
What's the difference between Grid computing and Cloud Computing
I don't clearly catch the difference betwenn these two concept. Someone told me that the essential différence is that the cloud computing give you a large space of storage and the grig give more advantages than storage, we can profit to much power with this last.
Does any one know more clearly these two concept; and tell us?
Views: 377
Replies to This Discussion
-
Permalink Reply by Thomas Michaud on
-
I don't claim to be the expert, but the difference is (I think) in use.
Grid represents a scalable framework. You write your algorithm and your code and use as much computing power as you wallet can afford. (Useful as some work can be highly parallelizable) .
Cloud computing offers storage (true) but it's also represents the applications as well. Ideally with cloud computing, you don't need to have certain applications on your desktop - as long as you can hit the cloud, you can get, update, and use your data.
-
-
Permalink Reply by Hervé-greg MOKWABO on
-
Thanks thomas;
What I got :
Grid - much computing power and can be highly parallelizable
Cloud - Storage and dont need to have certain applications on your desktop ( that's just like server application?)
Someone can tell us more?
-
-
Permalink Reply by Bradlee Sargent on
-
I think if you look at the history, you will understand some difference.
In my own experience, the grid began with Oracle using it as a type of metadatabase, which would point to multiple databases residing on different but uniform hardware systems. So if a company had multiple unix boxes and needed to increase the size of their database, instead of purchasing additional hardware they could implement the grid database and combine their multiple unix servers into one database resource.
Cloud is much more in terms of it offering not only a database, but also an entire server including the operating system.
The cloud exposes an operating system, whereas a grid exposes a database.
But I am no buzz word expert so I might be wrong.
-
-
-
I just talked to a buddy about this, essentially the Oracle Grid product is differant because it runs the DB in memory. So access times are a lot quicker. I don't think it is really a matter of Vs. so much as Grid computing is a way to handle db transactions in a faster way.
He said their grid servers had something like 72gbs of ram. Freaking crazy
-
-
-
Please Bradley, wha do you think about Jackie's reaction?
-
Happy 10th year, JCertif!
Notes
Welcome to Codetown!
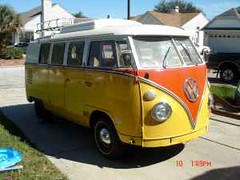 Codetown is a social network. It's got blogs, forums, groups, personal pages and more! You might think of Codetown as a funky camper van with lots of compartments for your stuff and a great multimedia system, too! Best of all, Codetown has room for all of your friends.
Created by Michael Levin Dec 18, 2008 at 6:56pm. Last updated by Michael Levin May 4, 2018.
Looking for Jobs or Staff?
Check out the Codetown Jobs group.
InfoQ Reading List
Reverse Engineer Anything Project Brings AI Agents to Binary Analysis
Reverse Engineer Anything (REA) is an open-source project with over 200K GitHub stars that connects coding agents such as Claude Code and Codex to reverse-engineering tools like Ghidra, Hopper, and IDA. The project lets developers inspect compiled binaries, trace function calls, and investigate how applications implement specific features.
By Renato LosioAmazon Acquires DuckLabs and Integrates DuckDB in Amazon Aurora PostgreSQL
Amazon has acquired DuckLabs, the company behind the analytical database DuckDB. Co-founders Hannes Mühleisen and Mark Raasveldt will continue to lead the team under AWS. The acquisition aims to enhance the development and reach of DuckDB while maintaining its open-source status. Amazon Aurora PostgreSQL gets its first DuckDB-powered feature following the acquisition.
By Gianmarco NalinGoogle EnvHarness Enables Self-Evolving Agents to Learn in Dynamics Environments
Google researchers open sourced EnvHarness, a framework that dynamically adapts agent-training environments to an agent's weaknesses without modifying the agent, environment, or evaluation system. According to the researchers, this approach can improve both learning effectiveness and efficiency while helping agents overcome their weaknesses.
By Sergio De SimoneZod Brings In-Process Schema Compilation and a 9x Cut in Memory Footprint
Zod is a TypeScript-focused schema validation library that recently released versions 4.5 and 4.6. Key updates include schema compilation for faster data parsing, significant memory usage reductions, and new validation features. The library supports efficient validation processes and remains popular in the JavaScript ecosystem, achieving millions of downloads weekly.
By Daniel CurtisUber Automates Dependency Analysis Across Its Service Mesh
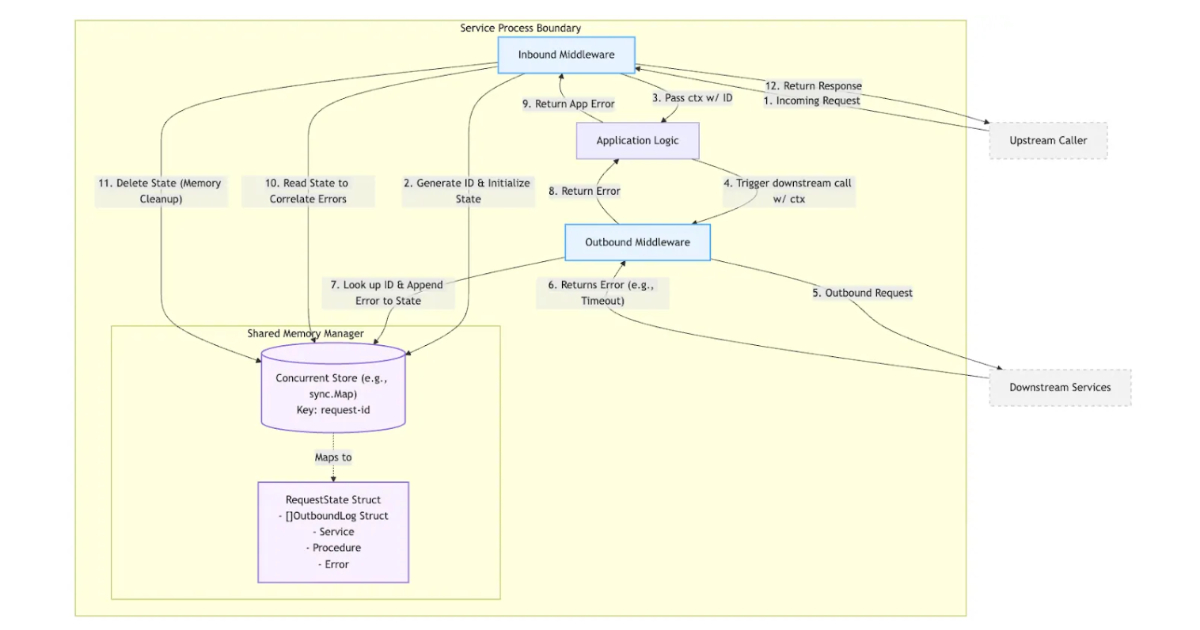
Uber has developed an automated dependency analysis system that uses RPC middleware and production metrics to correlate caller and downstream failures. The approach classifies dependencies as fail-close, fail-open, or unknown and addresses limitations of sampled distributed tracing for rare failures across Uber’s large service mesh.
By Leela Kumili
© 2026 Created by Michael Levin.
Powered by