Codetown
Codetown ::: a software developer's community
Kotlin Thursdays - Introduction to Functional Programming Part 2
Resources
- Higher-Order Functions and Lambdas:https://kotlinlang.org/docs/reference/lambdas.html
- FP in Kotlin Part 1: https://medium.com/kotlin-thursdays/functional-programming-in-kotli...
Introduction
Last week, we went over higher order functions in Kotlin. We learned how higher order functions can accept functions as parameters and are also able to return functions. This week, we will take a look at lambdas. Lambdas are another type of function and they are very popular in the functional programming world.
Logic & Data
Computer programs are made up of two parts: logic and data. Usually, logic is described in functions and data is passed to those functions. The functions do things with the data, and return a result. When we write a function we would typically create a named function. As we saw last week, this is a typical named function:
fun hello(name: String): String {
return "Hello, $name"
}
Then you can call this function:
fun main() {
println(hello("Matt"))
}
Which gives us the result:
Hello, Matt
Functions as Data
There is a concept in the functional programming world where functions are treated as data. Lambdas (functions as data) can do the same thing as named functions, but with lambdas, the content of a given function can be passed directly into other functions. A lambda can also be assigned to a variable as though it were just a value.
Lambda Syntax
Lambdas are similar to named functions but lambdas do not have a name and the lambda syntax looks a little different. Whereas a function in Kotlin would look like this:
fun hello() {
return "Hello World"
}
The lambda expression would look like this:
{ "Hello World" }
Here is an example with a parameter:
fun(name: String) {
return "Hello, ${name}"
}
The lambda version:
{ name: String -> "Hello, $name" }
You can call the lambda by passing the parameter to it in parentheses after the last curly brace:
{ name: String -> "Hello, $name" }("Matt")
It’s also possible to assign a lambda to a variable:
val hello = { name: String -> "Hello, $name" }
You can then call the variable the lambda has been assigned to, just as if it was a named function:
hello("Matt")
Lambdas provide us with a convenient way to pass logic into other functions without having to define that logic in a named function. This is very useful when processing lists or arrays of data. We’ll take a look at processing lists with lambdas in the next post!
Views: 211
Happy 10th year, JCertif!
Notes
Welcome to Codetown!
 Codetown is a social network. It's got blogs, forums, groups, personal pages and more! You might think of Codetown as a funky camper van with lots of compartments for your stuff and a great multimedia system, too! Best of all, Codetown has room for all of your friends.
Created by Michael Levin Dec 18, 2008 at 6:56pm. Last updated by Michael Levin May 4, 2018.
Looking for Jobs or Staff?
Check out the Codetown Jobs group.
InfoQ Reading List
Java News Roundup: TornadoVM 8.0, JNoSQL, Endive, JReleaser, JBang, LangChain4j, Quarkus Almanac
This week's Java roundup for October 26th, 2026, features news highlighting: the GA release of TornadoVM 8.0; point releases of JNoSQL, Endive, JBang, JReleaser and LangChain4j; a maintenance release of JobRunr; beta releases of Hibernate ORM and Hibernate Reactive; and introducing the Quarkus Almanac.
By Michael RedlichGoogle and Meta Open-source TorchTPU to Bring Native PyTorch Support to Google TPUs
TorchTPU is an open-source project developed by Google in collaboration with Meta that provides a native PyTorch backend for Google TPUs. It enables PyTorch workloads to execute on TPU hardware with minimal code modifications, supporting eager and compiled execution, distributed computing, and hardware-specific optimizations.
By Sergio De SimoneUber Builds MCP Gateway to Govern Access to 800+ Servers and 5,000+ AI Agent Tools
Uber has built an MCP Gateway to standardize how AI agents discover and invoke internal services across more than 800 MCP servers and 5,000 tools. The gateway separates tool registration from runtime execution and includes automated API discovery, access controls, sensitive data redaction, incremental tool discovery through Omni MCP, and response filtering.
By Leela KumiliPodcast: Educating an Architect: A Conversation with Luca Mezzalira
In this podcast, Michael Stiefel spoke to Luca Mezzalira about software architecture as a socio-technical discipline that balances technological design with an organization's social and managerial context. They explored how architectural choices must be adapted to a company's unique culture and team structure rather than relying blindly on universal best practices.
By Luca MezzaliraArticle: Systemic Approach to Memory, Knowledge, and Context in Agentic AI Architectures
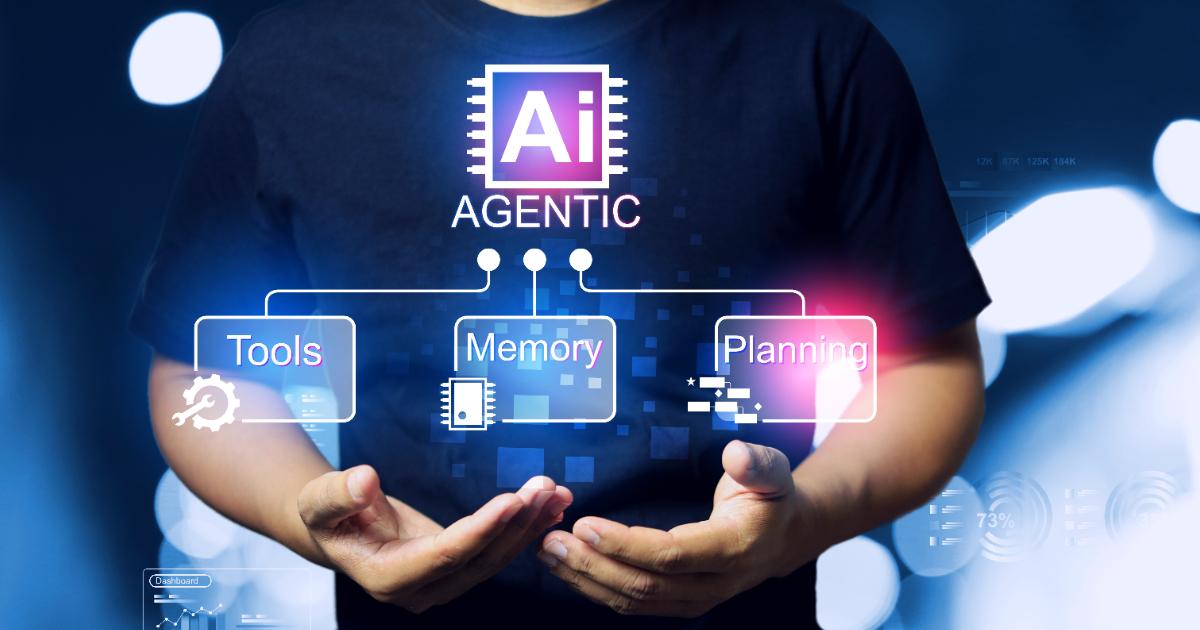
The article argues that reliable agentic AI architecture depends on a context engine that selects, injects, compresses, and expires information before it reaches the model. It separates context, memory, and knowledge, and recommends tiered memory, curated knowledge, and token budgeting. It also covers common anti-patterns, such as context stuffing and stale data loops, with mitigations.
By Adi Polak
© 2026 Created by Michael Levin.
Powered by

